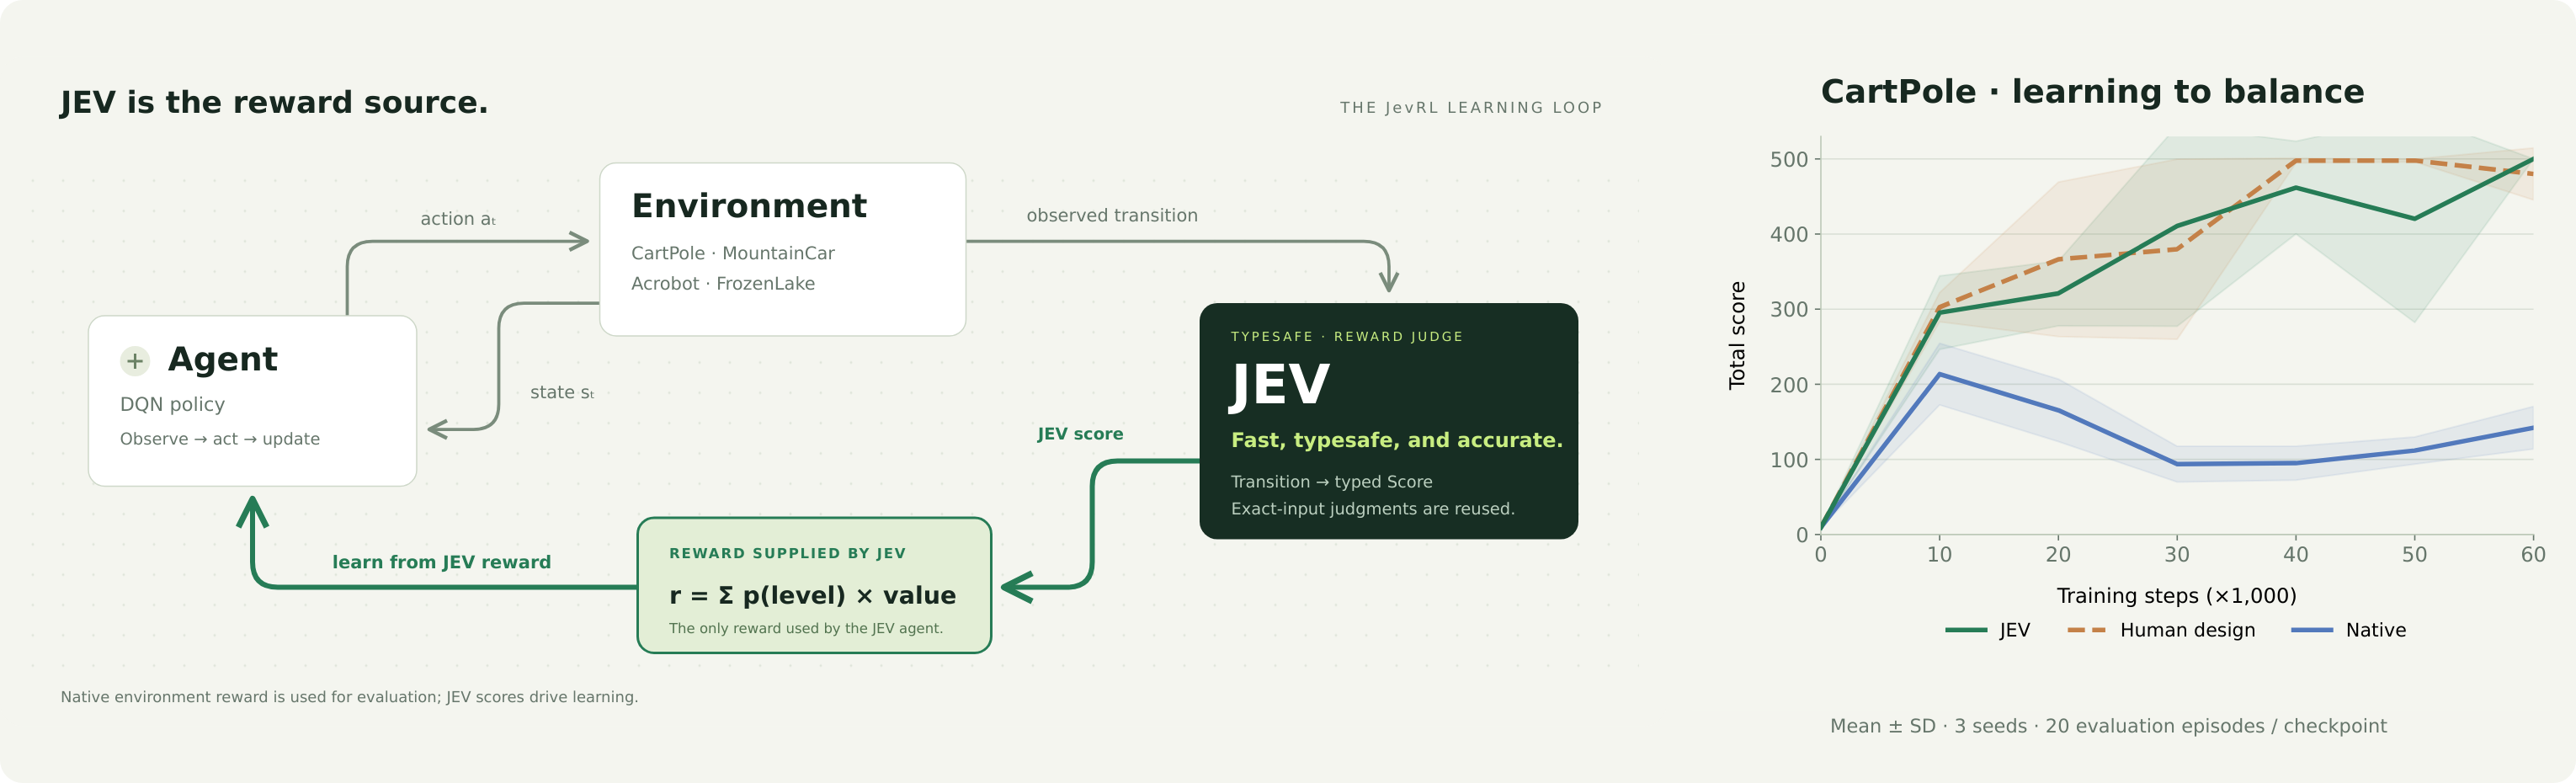
Total score
Original cumulative game score · development evaluation · mean ± training-seed SD
TYPESAFE JEV × REINFORCEMENT LEARNING
Fast, typesafe, and accurate.
JEV supplies the reward. The agent learns to play four classic games.
FROM FIRST ACTION TO FINAL POLICY
One game per column. One training stage per row.
Every reward comes from JEV. Every animation is a real saved rollout.
Training seed 7 · fixed replay seed 10000 · complete episodes, time-compressed. Rows use actual environment steps. Final budget: CartPole / FrozenLake 60k; MountainCar / Acrobot 120k. A replay is one episode; the CartPole curve above averages three training seeds. Scroll sideways on mobile to compare all four games.
EXPLORE THE EXPERIMENT
Inspect every checkpoint, compare reward sources,
or start a fresh local training run.
CLASSIC CONTROL
MEASURE WHAT THE AGENT ACTUALLY ACHIEVES
Training scores have different scales.
Compare policies using total score and success rate.
Shaded bands show variation across training seeds.
Original cumulative game score · development evaluation · mean ± training-seed SD
Development evaluation · mean ± training-seed SD
Selected run · per-episode return and a 20-episode moving mean
Protocol: 3 training seeds · equal step budgets within each game · 20 development episodes per checkpoint · 100 disjoint final test episodes. Observations and rubrics are human-designed. These experiments measure a reward integration, not a new RL algorithm or a claim of general game intelligence.